What Is RAG? Retrieval-Augmented Generation Explained
By
Tom Dallimore
Published

Retrieval-augmented generation (RAG) is a technique that retrieves information from external sources and gives it to an AI model as context before it answers. It lets the model use relevant documents, company knowledge or current records alongside what it learned during training, without retraining it whenever that information changes.
Think of it as giving your AI something useful to read before asking it a question. Fairly reasonable thing to do, really.
A language model can explain what a refund policy usually looks like. Ask it about your company’s policy, though, and where is it supposed to get that information? It hasn’t read the document sitting in your Google Drive. RAG gives the application a way to find that document and use the relevant bits to answer.
I’m Tom, the founder of Fetch Hive. In this guide, I’ll explain how RAG works without making you sit through a lecture on vector maths. We’ll cover where it helps, what can still go wrong, and where to go next if you want to build something useful.
What does RAG stand for?
RAG stands for retrieval-augmented generation. It sounds more complicated than the basic idea actually is:
Retrieval: find information relevant to the question.
Augmentation: add that information to the model’s input.
Generation: use the model to produce an answer from that context.
One thing to get straight early: uploading documents to a RAG knowledge base does not normally train the language model on them. The documents stay in a separate source that your application searches when needed. RAG describes that approach, rather than a particular model you buy.
How does RAG work?
Suppose someone asks, “Can I return a product after opening the packaging?”
A basic RAG system handles the question in five steps.
Receive the question. The application takes the user’s request and any relevant conversation context.
Search the available sources. It looks for the return policy and any exceptions that apply to opened products.
Select useful evidence. It chooses relevant passages, checking things such as the product, policy version and the user’s access permissions.
Give the model the context. It sends the question, useful passages and instructions to the language model. Those instructions can tell it to cite its sources and say when it doesn’t have enough information.
Generate the answer. The model explains the policy using the supplied information. The application can include links to the passages so the user can check them.
That fourth step is the augmentation. You’ve given the model information to work with before it answers. You haven’t retrained it every time someone asks about opened packaging. Thankfully.
There’s some preparation before any of this happens. Documents need to be imported, cleaned, split into useful passages and indexed so the system can search them. When a policy changes, that index may need updating too. A new file in your company folder is no use if the search system is still reading the old one.
If you want to see what happens at each stage, I’ve broken it down in How to Build a RAG Pipeline: Ingestion to Generation.

RAG vs a language model on its own
On its own, a language model works with what it learned during training and whatever you put into the conversation. RAG lets the application go and find additional information before asking the model to answer.
Information available. Without retrieval, the model uses its training knowledge and the conversation context. With RAG, the application can also bring in relevant information from connected sources.
Private policies. Either approach can use a policy you supply in the conversation. RAG can retrieve it from connected sources when the user has access.
Updates. Without retrieval, you need to provide new information in the conversation. RAG can use refreshed indexes or a live source, if the application connects to one.
Source references. A model can cite sources you give it. A RAG application can attach references to the evidence it retrieved.
Accuracy. Both can be wrong. RAG can also fail when retrieval returns poor evidence.
Some chatbots already have retrieval built in, so this isn’t a competition between model brands. You can use the same language model with or without RAG. The difference is whether your application goes looking for evidence first.

What are the components of a RAG system?
You don’t need to understand every implementation detail yet, but it helps to know what’s doing what. Most document-based RAG systems have these pieces:
Knowledge sources: the documents, help articles, records or other information the application can access.
Ingestion and indexing: getting your information into a searchable form, with useful details such as dates, headings and permissions attached.
A retriever: the search component that finds evidence relevant to a request.
The prompt and retrieved context: the question, selected passages, source references and instructions you send to the model.
A language model: the component that turns the question and evidence into an answer.
You also need to test the whole thing. Did it find the right passage? Did the answer actually follow what that passage said? A response that sounds sensible isn’t much of a test. Language models are already very good at sounding sensible.
You’ll hear a lot about embeddings and vector databases. They’re common ways to make retrieval work, but RAG doesn’t require them in every setup. Keyword search, database queries and other retrieval methods can supply the information too.
For the deeper explanation of how it all fits together, read RAG Architecture: How a Production RAG System Actually Works.
Why use RAG?
RAG becomes useful when the answer depends on something specific to your business, or something that has changed since the model was trained.
Your own information. Your internal processes, product manuals and customer agreements are unlikely to be in a general model’s training data. RAG lets the application find the relevant information when someone needs it.
Information that changes. Update a connected source or index and the application can retrieve the new information without retraining the model. Just remember that “up to date” depends on how often you actually update it. RAG won’t maintain your documents for you.
Answers people can check. Keep the source references and you can show users where an answer came from. That’s useful when someone wants to check a policy before acting on it. You still need to verify that the cited passage actually supports the answer, though.
Fewer opportunities to make things up. Giving the model relevant evidence can reduce hallucination risk. You can also instruct it to say when the sources don’t answer the question. It can still get things wrong, but at least you’re giving it something solid to work with.
None of this is free. Search, storage, indexing and model calls all cost something. Whether RAG saves you money depends on the work it replaces and how you build it. There isn’t a universal “add RAG, reduce bill” button.

A simple RAG example in customer support
Imagine a customer asks, “My package hasn’t arrived. Can I get a replacement?”
A generic answer like “Please check your tracking number” is going to be fairly annoying if the customer has already done that six times. A useful assistant needs the replacement policy and the actual status of this customer’s order.
It could retrieve the policy from a knowledge base, then check the order or carrier system through an authorised lookup. That second bit matters. Uploading last week’s tracking spreadsheet doesn’t suddenly give your AI live tracking data.
Let’s say those sources show:
The latest carrier update shows a delay, rather than a lost parcel.
The company allows replacement requests after seven days without a tracking update.
This order’s last update was three days ago.
Now the assistant can explain what’s happening and when a replacement can be requested, with references to the policy and tracking record. The customer gets an answer about their order instead of another generic paragraph about how delivery works.
If the tracking lookup fails, the assistant should say it couldn’t check the current status and offer a sensible next step. A confident invented delivery date is still an invented delivery date.
Common RAG use cases
Customer support is one example. RAG also fits internal knowledge assistants, technical documentation search, research across large document collections, and questions about contracts or policies.
I’d start with a simple question: does this task need information from a particular source? If employees keep digging through the company wiki for answers, retrieval could help. If you just want a model to rewrite a paragraph, you probably don’t need to build a knowledge base around it.
The right information still needs to be available, and the user needs permission to see it. A document matching the question doesn’t mean everybody should have access to it.
I’ve covered the applications and company examples separately in 7 real-world RAG use cases.

Where embeddings and vector databases fit
People rarely phrase a question exactly as it appears in a document. Someone might ask how to “close my account” when the help article calls it “cancelling your subscription.”
Embeddings turn text into lists of numbers that help a search system match related meanings. A vector database or vector index stores and searches those representations, then returns the associated passages. You don’t need to do the maths yourself to understand the job it’s doing.
The embedding model creates the vectors. The database searches them. Neither component writes the final answer.
Exact wording still matters sometimes. If someone asks about error code FH-2047, a passage about a vaguely similar error might be useless. That’s why systems often combine search by meaning with keyword search and filters.
If you want to understand those pieces properly, read RAG Embeddings Explained and Vector Databases for RAG: What Matters and How to Choose.
What is agentic RAG?
Agentic RAG gives an AI agent more control over retrieval. It can decide which source to query, break a question into smaller searches and retrieve again when the first results do not provide enough evidence.
That helps when a question needs several sources or the first search turns up incomplete information. But each extra search or decision can add cost, delay and another thing to debug. You probably don’t need a committee of AI agents to find out how many days someone has to return a toaster.
For questions that do need that extra work, I cover the planning and verification process in Agentic RAG Explained: How RAG Agents Plan, Retrieve and Verify.
RAG limitations and how to improve results
RAG can still give you rubbish answers. Retrieve an old policy, cut off an important exception or send the model a barely relevant passage, and it may confidently explain the wrong thing. Lovely.
Even when the evidence is good, the model can misread it. More search and model calls can make the system slower or more expensive, too. And private content needs access controls before it reaches somebody who shouldn’t see it.
Test questions people will actually ask. Look at what the system retrieved, then compare the answer with those passages. Include questions your documents cannot answer as well. You want to know whether the assistant admits it doesn’t know or starts inventing a policy on your behalf.
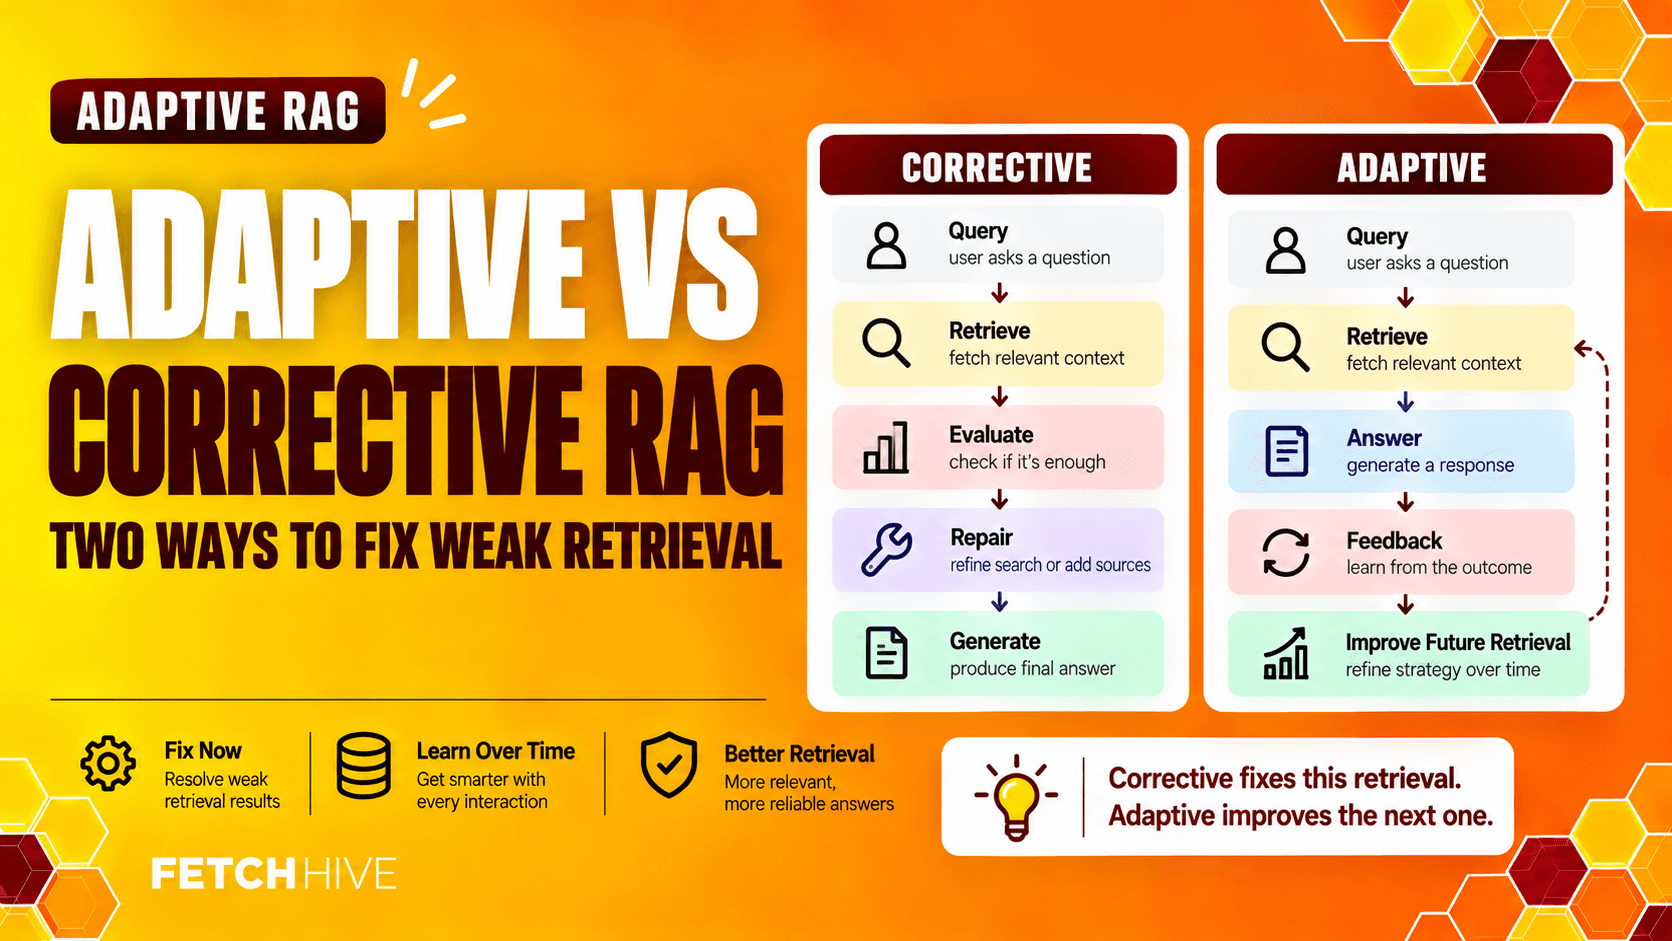
If your system is already built but the answers aren’t good enough, start with How to Improve RAG Performance. For approaches that change how the system retrieves information or responds to weak results, read Adaptive RAG vs Corrective RAG.

Frequently asked questions
Is RAG the same as fine-tuning?
No. RAG supplies retrieved information as context at answer time. Fine-tuning updates model weights through additional training. Fine-tuning can help with behaviour or specialised tasks; RAG is often useful for information that changes or needs source attribution. You can use both.
Does RAG eliminate hallucinations?
No. Giving the model relevant evidence can help, but it can still retrieve the wrong information or generate an unsupported answer. Check what it found, whether the answer matches, and what it does when the information is missing.
Does RAG need a vector database?
No. Vector search is common, but the defining feature is retrieving external information and using it during generation. Other search methods and structured lookups can provide that context.
Is semantic search the same as RAG?
Semantic search finds information based on meaning. RAG uses retrieved information to generate an answer. Semantic search can be one part of a RAG application.
Does RAG always provide real-time information?
No. If your knowledge base was last refreshed a month ago, that’s the information it has. Live answers need a connection to a source that can provide current information when the question is asked.
Do larger context windows remove the need for RAG?
For a small set of documents, supplying everything directly may be practical. Retrieval remains useful when the collection is large, changes often, has access restrictions or would be expensive to include in every request.
Where to go next
Start with one question your users need answered. Find the information that answers it, then check whether your system can retrieve it and explain it correctly. You’ll learn more from that than from spending a week comparing impressive architecture diagrams.
And if you want to build agents and workflows around your own knowledge, take a look at Fetch Hive. That’s what I’m building it for.
Share this post